Field note · AI Engineering · · 3 min read
Give a coding agent work small enough to verify
Picture a coding agent asked to “build the publishing workflow” for a hypothetical editorial tool. The agent must settle questions nobody wrote down, such as what counts as a saved draft and what happens when a save fails. You discover its answers in review, spread through one large change.
Hand over a slice instead: one behavior the agent can finish and you can verify, with its boundaries and evidence agreed before any code changes.
Write the brief from the current code
Read the current code and tests before writing the brief. Last week's plan may ask for work that already shipped. If it calls for a drafts table that already exists, fix the plan before the agent reads it.
A sensible first slice lets an editor save a draft and get the same content back after a reload. Its brief also names what must keep working and what waits for later. Write ambiguous cases, such as a failed save, as Given/When/Then examples so the agent does not have to guess.
That slice runs from the editor screen to the database. Crossing those layers can still be manageable when a reviewer can check one behavior end to end. Google's code review guidance (opens in a new tab) puts the right size at one self-contained change with its related tests, and suggests smaller full-stack features as one way to split work. Google also counts lines and files, so one behavior spread across fifty files deserves a second look.
A brief for the draft-save slice
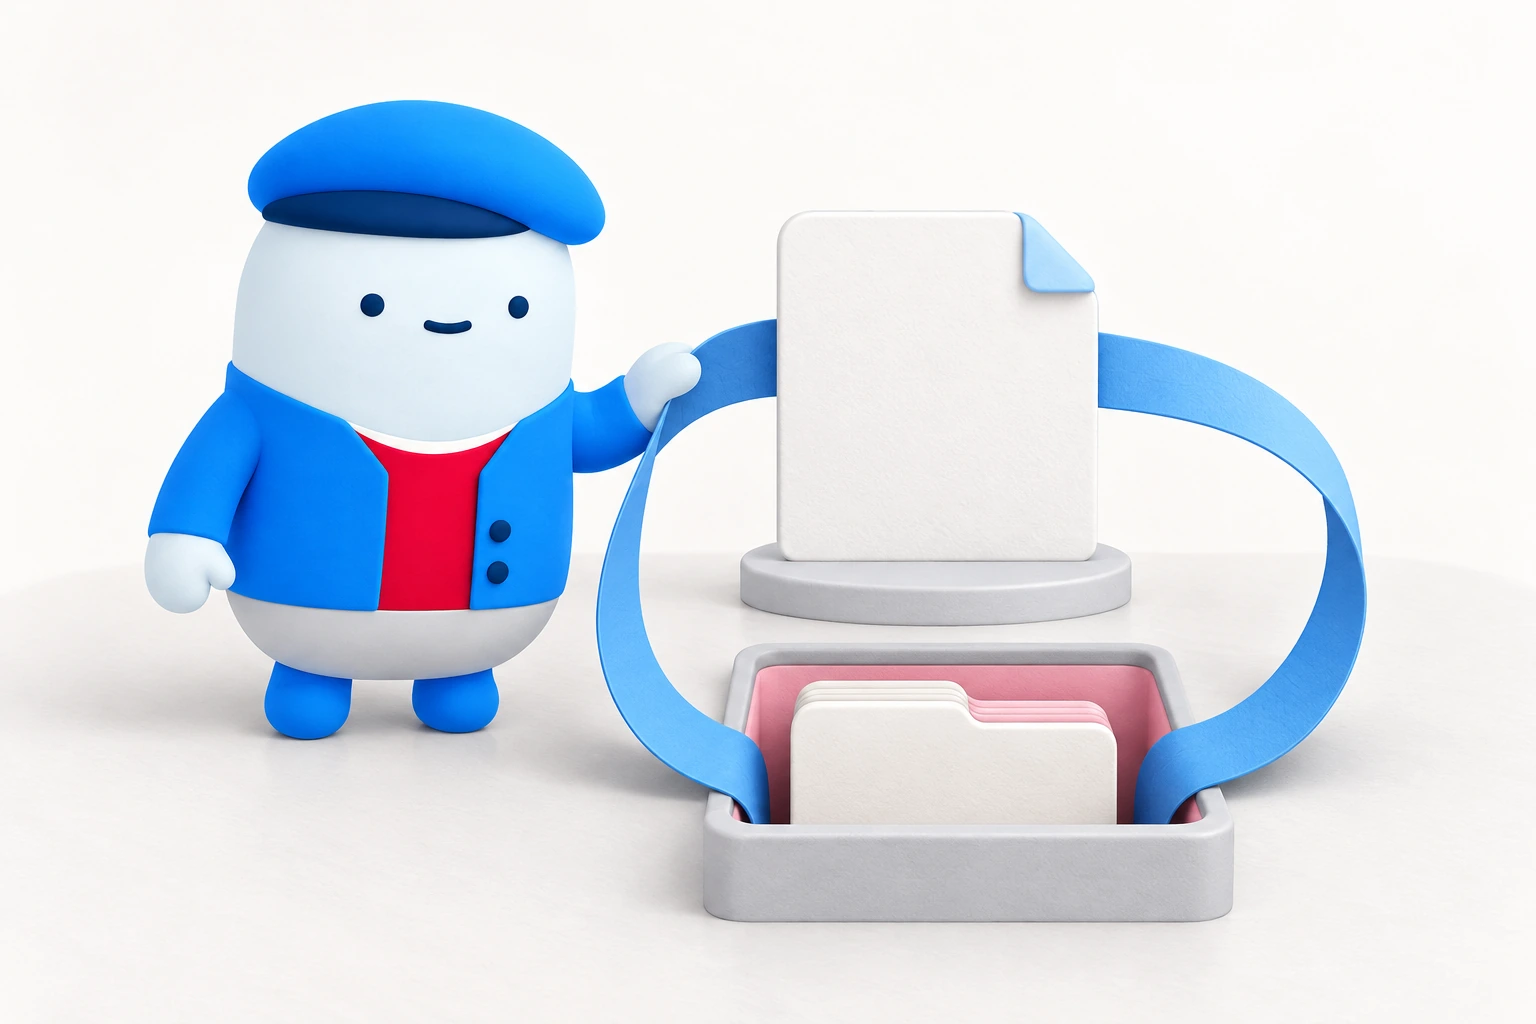
The draft-save slice runs from the editor to storage and back to the editor.
Outcome
An editor saves a draft, reloads the page, and gets the same content back.
If saving fails
Given unsaved changes, when the save fails, then the text stays in the editor and a message says the draft was not saved.
Boundaries
Published posts and editing permissions work as before. Approval routing and scheduled publication wait for later slices.
Evidence
Tests cover save/reload, failed saves and access. Browser checks cover the editor and published posts. Record the results.
Check each slice before starting the next
Small slices help only if each one is checked as it lands. DORA's guidance on small batches (opens in a new tab) warns that AI tools are often optimized to generate large, complete features, and that machine-generated code may take more review effort per line than human-written code. Regrouping small batches before testing, it adds, delays feedback on defects. A week of slices saved for one review is that kind of regrouping.
The brief's evidence tells the agent what it must demonstrate. Anthropic's best practices for Claude Code (opens in a new tab) note that without a check it can run, the agent's only signal is that the work looks done. The guide recommends stating excluded work and finishing the specification with a check of the whole feature.
Protect those checks while the agent works. If the editor loses text on a failed save, first watch a test catch that loss. Run it again after the fix. If changing a test's expectation would change the agreed behavior, revisit the brief. Adapt our two-account test to check both an allowed save and a refused save at the server. Then compare the diff with the brief and remove unrelated changes.
When the slice is done, update the documentation that owns any changed behavior or decision, such as a decision record or the agent's instructions file. Point the next brief to that updated record. Record what was verified and what is still open, keeping a local pass separate from a merge or a deploy, since each needs its own check.
A typo fix needs no brief, and Anthropic's guide suggests skipping the plan when you could describe the diff in one sentence. An unfamiliar integration may need a short investigation before it can be sliced, with a question to answer and a point where it stops.
Use what each slice teaches you in the next brief. A case the tests missed, or a decision the agent had to guess, usually belongs there before the agent starts again.
Written by the Moga principals.
More from AI Engineering
- 2 min read
Review an agent skill like a software dependency
Trace what a shared agent skill can run and access before your team installs it.
- 2 min read
Treat a model upgrade like a permission change
Before switching models, give both the same task on a safe copy and compare what each tries to change.